Agility is no longer a label, it’s an operational capability.
Scrums that drag on, sprints that overflow, technical debt that slows down roadmaps: despite modern tooling, many organizations struggle to deliver fast and well. The main cause is not the method, but execution capacity: talent availability, 24/7 coverage, industrialized run operations, end-to-end automation.
This is exactly where well-governed offshore IT changes the game: by bringing specialized skills, elastic capacity, multi-time-zone coverage and engineering discipline (CI/CD, QA, SRE, FinOps), it allows CIOs to anchor agility in the reality of deliveries.
1) Definition: what do we mean by “well-governed offshore IT”?
- Offshore IT: IT activities (Build/Run/Cyber/Data/Cloud) carried out by teams located in distant time zones (e.g. Asia, Indian Ocean, Africa).
- Well-governed: demanding governance on the client side (RACI, KPIs, security, DPA/GDPR), a shared toolchain (backlog, CI/CD, ITSM, observability), clear contracts (SLA/SLO, reversibility, IP), aligned cadences and rituals.
The goal is not to “do it cheaper”, but to do it better, faster and repeatably, while reallocating budget to product innovation.
2) Why offshore accelerates agility (when it’s well governed)
2.1 Immediate access to critical skills
Cloud, security, data/AI, test automation, SRE: offshore opens up talent pools where this expertise is available on demand, with communities used to industrialization.
Result: fast ramp-up without endless recruitment cycles.
2.2 Elasticity and capacity smoothing
Peaks (cloud migration, product scale-up, compliance work) are absorbed without inflating payroll. Ramp-down is just as simple.
Agility stops being theoretical: your delivery cadence becomes predictable.
2.3 24/7 coverage and follow-the-sun
An incident at night? A patch outside business hours? The time difference becomes an operational advantage: SRE, SOC, monitoring and support work in relay, for a compressed MTTD/MTTR and calmer deployments.
2.4 Cost efficiency reinvested in innovation
The cost difference directly funds automation (tests, pipelines, IaC), continuous improvement (SRE) and the product roadmap. You accelerate while raising quality.
2.5 Execution discipline
Good offshore centers live by SOPs, runbooks, policy-as-code and post-mortems. This culture of repeatability stabilizes your operations and makes your releases more reliable.
3) The agility levers activated by offshore
- Time-to-value: the ability to onboard several squads in parallel, accelerating the delivery of priority features.
- Built-in quality: test automation, code reviews, Sonar, SLOs; offshore makes it possible to industrialize what in-house teams don’t have time to do.
- Observability: APM, logs, metrics, traces; correlation and alerting for fast learning.
- SRE & toil reduction: less repetitive work, auto-remediation and error budgets for smart trade-offs.
- FinOps: showback/chargeback, rightsizing, reservations/commitments; agility costs less and stays under control.
4) Operating model for “agile-by-design” offshore
4.1 Delivery organization
- Two- or three-shore squads: a PO/PM and a reference architect on the client side; dev/QA/SRE can be offshore.
- RACI: who decides, who executes, who validates.
- Rituals: daily (Build), weekly ops (Run), CAB for major changes.
4.2 Cadences & overlap windows
- A daily golden hour (2–3 h) for decisions, demos and pair work.
- Standardized handover (handover template) between time zones.
4.3 Shared toolchain
- Backlog (Jira/Azure DevOps), CI/CD (trunk-based, pipelines), ITSM (ServiceNow/JSM), observability (APM/logs/metrics/traces), CMDB, secrets management.
- JIT/JEA access, MFA, bastion; centralized logging (SIEM).
4.4 Living documentation
- Runbooks/SOPs, architecture diagrams, ADRs (Architecture Decision Records).
- Without living documentation, there is no lasting agility.
5) The technical practices that make the difference
- Robust CI/CD: reproducible builds, tests with thresholds, canary/blue-green deployments, feature flags.
- Test automation: unit, integration, E2E, performance, security (SAST/DAST/IAST).
- Infrastructure-as-Code & platform engineering: ephemeral environments, golden paths for developers.
- SRE: SLOs, error budgets, blameless post-mortems, toil < 50%.
- Observability: service level indicators, correlations and meaningful alerts.
- Security by design: threat modeling, SBOM, dependency checks, managed secrets.
6) Governance and security: the keystone
6.1 Governance
- Weekly committee (operational): incidents, capacity, debt, actions.
- Monthly committee (tactical): KPI trends, trade-offs, risks.
- Quarterly committee (strategic): trajectory, business case, improvement roadmap.
6.2 Contracts and compliance
- DPA/GDPR, data location, sub-processors, IP (code, pipelines, models).
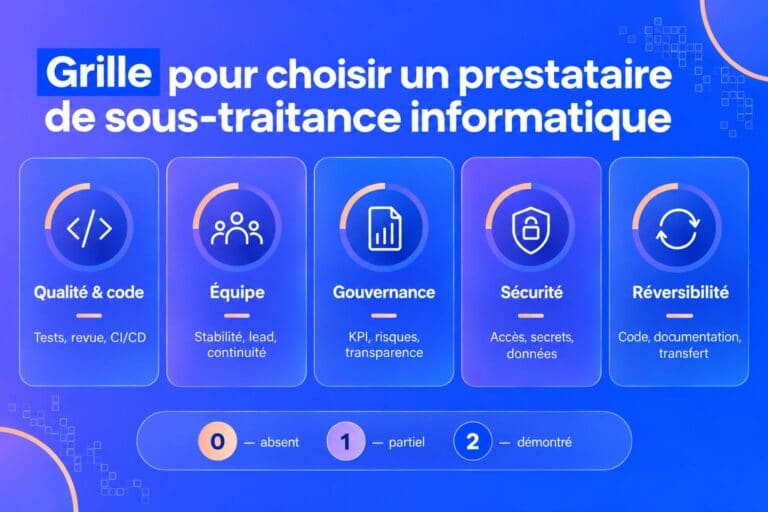
- Reversibility: deliverables, schedule, costs, go/no-go.
- SLA/SLO: bonus-malus aligned with business value (availability, MTTR, FinOps savings).
7) How to measure agility (and continuously improve it)
7.1 KPIs “that help you decide”
- Build (DORA): lead time, deployment frequency, failure rate, MTTR.
- Quality: test coverage, defect escape rate, change failure rate.
- Run/SRE: availability, MTTR, share of auto-remediation, incident debt.
- Security: security MTTD/MTTR, critical patches < 7 days, open “critical” findings.
- FinOps: recurring savings, variance vs. budget, cost per business unit, zombies < 3%.
- Product: NPS, feature adoption, time-to-impact.
7.2 Improvement loop
- 1 KPI = 1 decision: each indicator must trigger an action.
- Blameless post-mortems: structured learning.
- Improvement backlog: prioritized by economic impact and risk.
8) Use cases (illustrative) that demonstrate the agility gain
8.1 24/7 monitoring & SRE for an e-commerce platform
- Before: night-time incidents slow to detect, risky night deployments.
- After: offshore relay, SLOs and runbooks; canary deployments, compressed MTTR, increased release frequency.
8.2 Progressive modernization of a monolith
- Before: fragile pipeline, low test coverage, monthly releases.
- After: strangler pattern, contract tests, robust CI/CD, weekly or even daily cadence, technical debt under control.
8.3 Managed FinOps
- Before: over-provisioning and volatile costs.
- After: rightsizing, scheduling, reservations/commitments; showback/chargeback; recurring savings reinvested in features.
8.4 Multi-time-zone managed SOC
- Before: slow detection, inconsistent remediation.
- After: SIEM + EDR, incident playbooks, crisis exercises, tighter MTTD/MTTR.
9) Anti-patterns: what breaks agility
- Vague contract (implicit scope/expectations).
- Price hunting without quality requirements or governance.
- Unorchestrated multi-sourcing (diluted responsibilities).
- No JIT/JEA access and no centralized logs.
- “Documentation later”: key knowledge not captured.
- Vanity KPIs with no decision-making power.
10) 90-day roadmap for agile offshore
Weeks 1–2 — Scoping
- Pilot scope, risks, assumptions, SMART objectives (e.g. MTTR < 60 min, +30% release frequency, -15% cloud cost per unit).
- Choice of 5–7 decision-making KPIs.
Weeks 3–6 — Selection & preparation
- Short, targeted RFP (references, security, ramp-up, pricing model, governance).
- Tooling audit: backlog, CI/CD, ITSM, observability.
- Security upgrade: SSO/MFA, bastions, least privilege, secrets management.
Weeks 7–10 — Pilot & hypercare
- Two-/three-shore squads, rituals, golden hour.
- Canary deployments, runbooks, SLOs.
- Shared dashboard, continuous improvement actions.
Weeks 11–12 — Decision
- Review of objectives, operational ROI, residual risks.
- Decision on progressive extension (and possibly B.O.T.: Build-Operate-Transfer).
11) Ready-to-use checklist
- Clear, quantified business objectives.
- RACI defined and executive sponsor identified.
- Shared toolchain (backlog, CI/CD, ITSM, observability).
- Security by design (DPA/GDPR, JIT/JEA access, SIEM).
- SLA/SLO tied to value (availability, MTTR, cost per unit).
- KT plan (shadowing → reverse shadowing → takeover).
- Contractual reversibility & IP defined.
- Improvement loop (post-mortems, quarterly backlog).
- Communication (cadences, golden hour, standardized handovers).
Well-governed offshore: from the promise of agility to measured agility
Agility isn’t just a methodological framework: it’s the ability to deliver business value frequently, reliably and at a controlled cost. Well-governed offshore IT provides the missing building blocks: available talent, elasticity, 24/7 coverage, engineering discipline and outcome-driven governance.
By combining CI/CD, SRE, test automation, FinOps and security by design, CIOs turn a cost advantage into a competitive advantage: more speed, more quality, fewer risks and an IT department refocused on product value.
Want to accelerate your roadmap and stabilize your operations without losing control?
- Launch an 8–12-week pilot on a high-value scope.
- Set 5–7 KPIs tied to decisions.
- Require simple but real governance and documented reversibility.
Contact Etixio to get started now.
FAQ
Does offshore IT mean losing control of an IT project?
No, provided that steering is properly structured. In a well-governed offshore IT model, the client keeps the key decisions, such as product prioritization, architecture choices and security governance.
Offshore strengthens execution capacity without undermining control.
Can you do agile or DevOps with offshore teams?
Yes, offshore IT is compatible with agile methods and DevOps, and it’s even an accelerator when well organized.
Offshore increases delivery capacity, provided you rely on a shared toolchain, clear responsibilities and daily synchronization time between teams.
Which IT activities should be outsourced offshore to maximize performance?
Offshore IT is particularly effective when used in a targeted and structured way.
External teams provide strong leverage on activities that can be industrialized, such as QA, SRE, CloudOps or FinOps, as well as on specialized expertise that is hard to mobilize quickly in-house.
On the client side, the challenge is to keep steering functions such as product vision and architecture trade-offs, in order to align offshore execution with business objectives.
How do you structure an offshore collaboration so that it stays effective over time?
Performance rests on three pillars:
- clear governance (RACI, KPIs),
- a shared toolchain (CI/CD, backlog, observability)
- and living documentation.
These elements ensure a collaboration that is smooth, measurable and continuously improvable.
How long does it take to see agility gains with offshore IT?
The first gains can appear within the first few weeks, particularly in production capacity and operational coverage.
However, a lasting improvement in agility generally takes 2 to 3 months, the time needed to stabilize governance, tools and collaboration processes.